LLM Serving Capacity: KV Cache, Concurrent Users and Queue
 Wired White v1
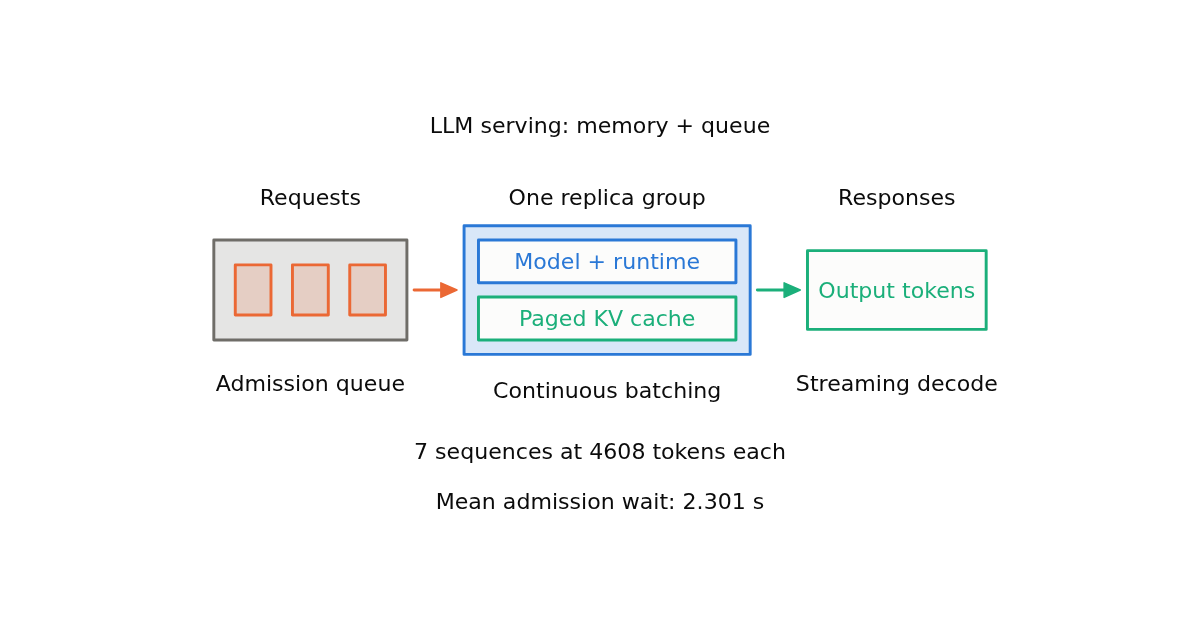
Estimate KV cache capacity, concurrent requests, queue delay and streaming latency. Compare parallel agent completion and cost against local server and API limits.
Wired White v1 Estimate KV cache capacity, concurrent requests, queue delay and streaming latency. Compare parallel agent completion and cost against local server and API limits.
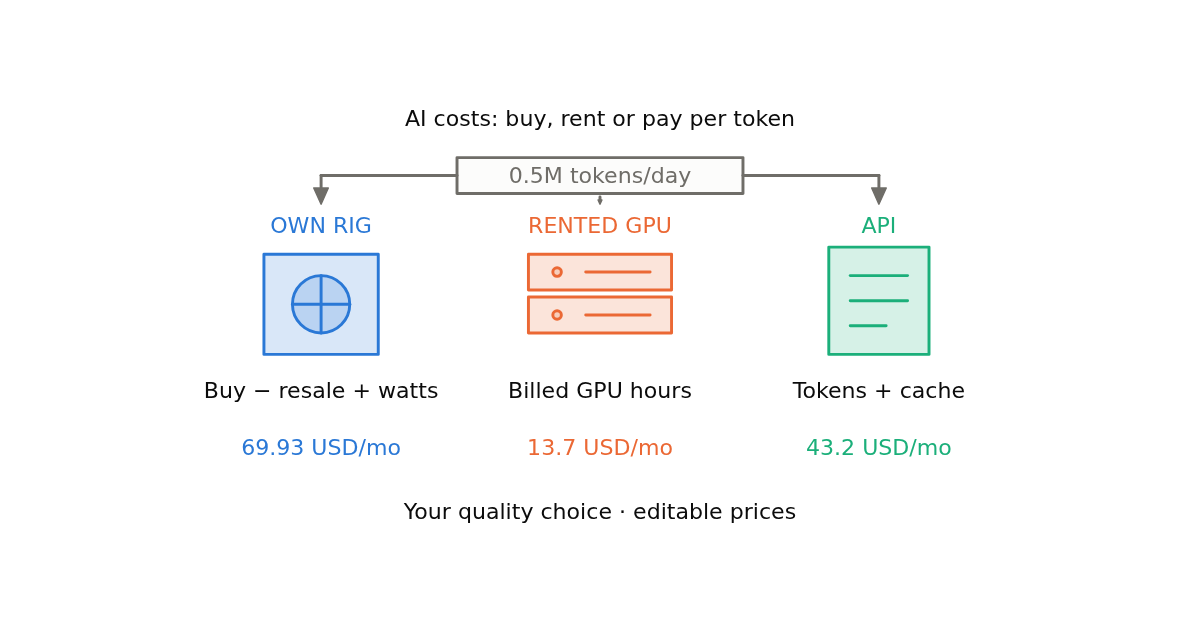
Wired White v1 Compare owning an AI rig, renting a GPU and using an API. Include prefill, decode, idle power, resale, upkeep, caching and reasoning tokens to find cost per million tokens and break-even.
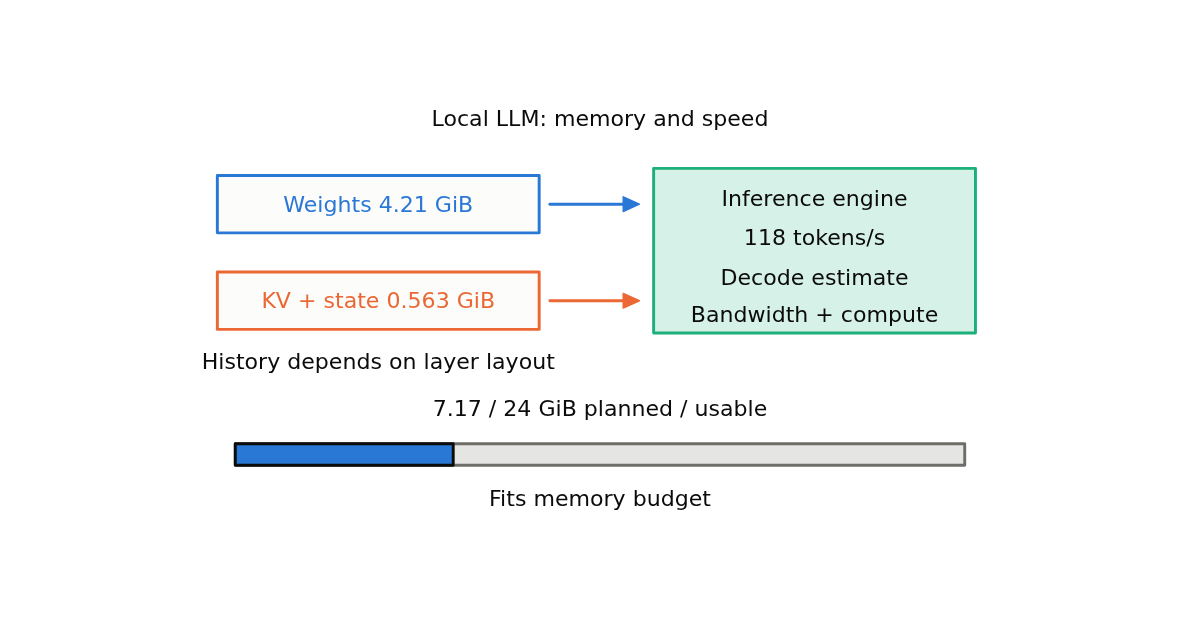
Wired White v1 Find which local LLMs fit your GPU, Mac or CPU—or which hardware fits a model. Compare KV memory, prefill, decode, runtime support and measured speed references.






Please confirm you want to block this member.
You will no longer be able to:
Please allow a few minutes for this process to complete.