AI Training Power Swings, Grid Oscillations and BESS Sizing
 Wired White v2
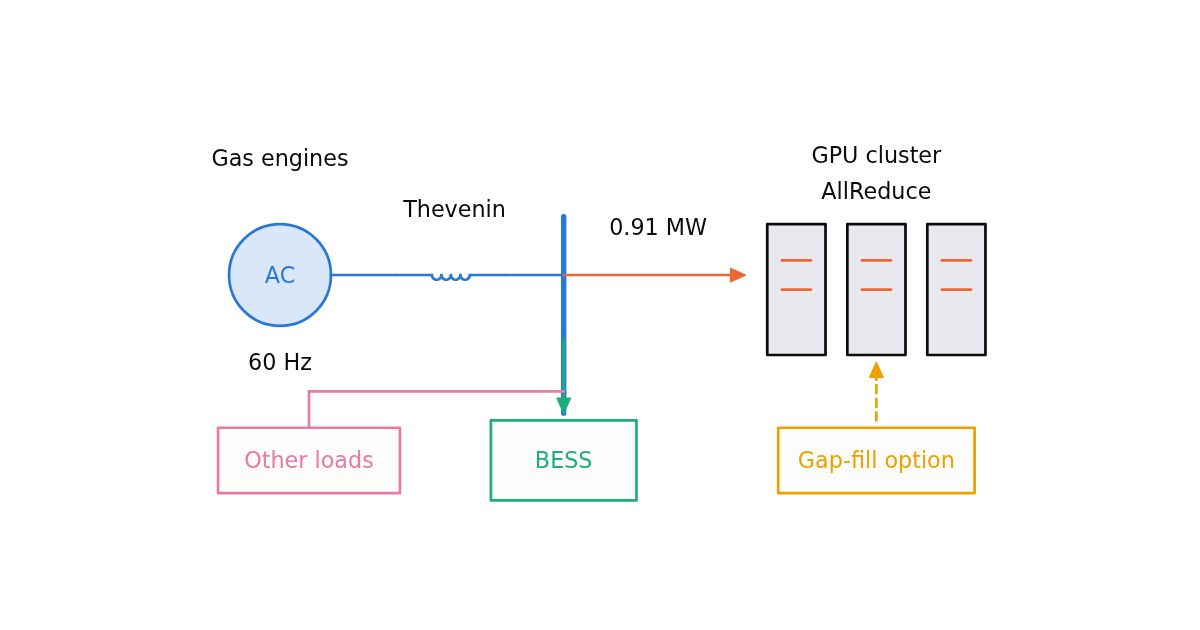
Model synchronized GPU training pulses, source frequency and bus voltage. Size ramp-limited BESS power and energy, and compare the energy cost of dummy-load gap filling.
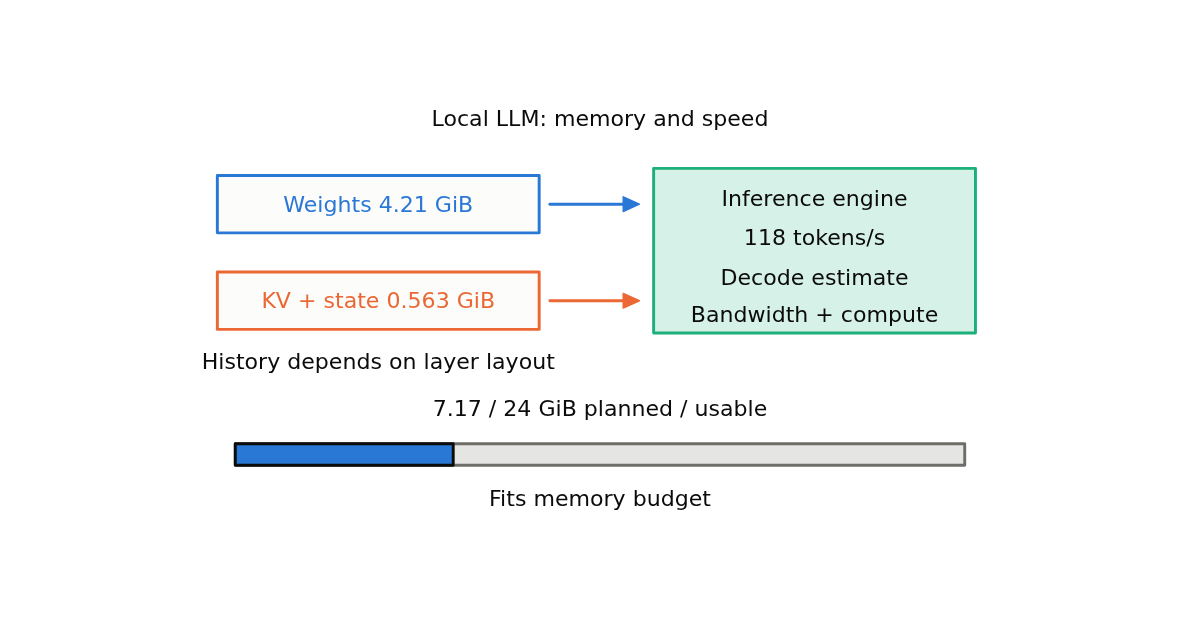
Hardware sizing for AI: how much GPU memory and speed a language model needs for its size, quantization and context length.
Wired White v2 Model synchronized GPU training pulses, source frequency and bus voltage. Size ramp-limited BESS power and energy, and compare the energy cost of dummy-load gap filling.
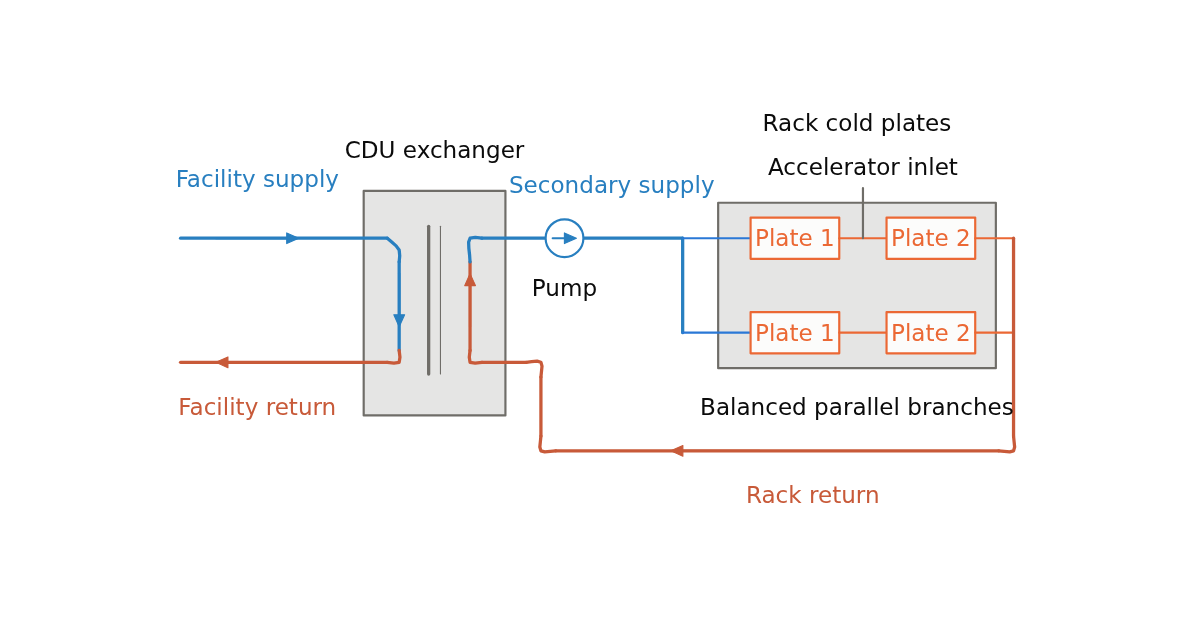
Wired White v3 Size rack cooling flow, pressure drop and pump duty. Calculate CDU exchanger approach with ε–NTU and fouling, then check the accelerator coolant inlet limit.
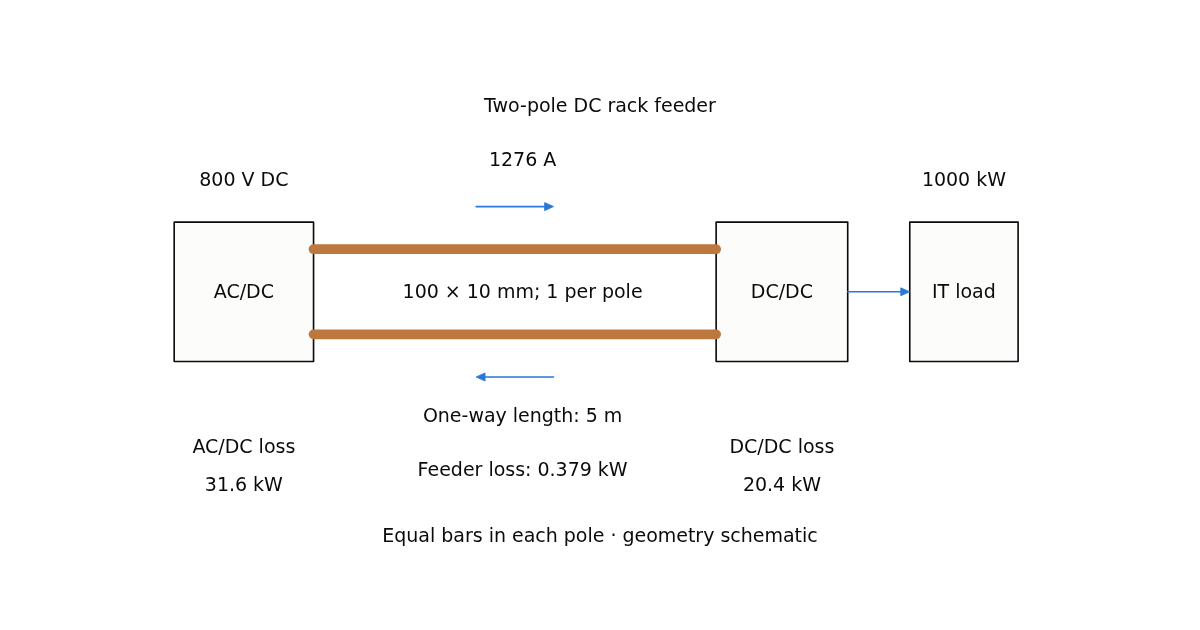
Wired White v2 Size a two-pole DC rack feeder, calculate converter and busbar losses, and explore source fault-current rise for an 800 V power architecture.
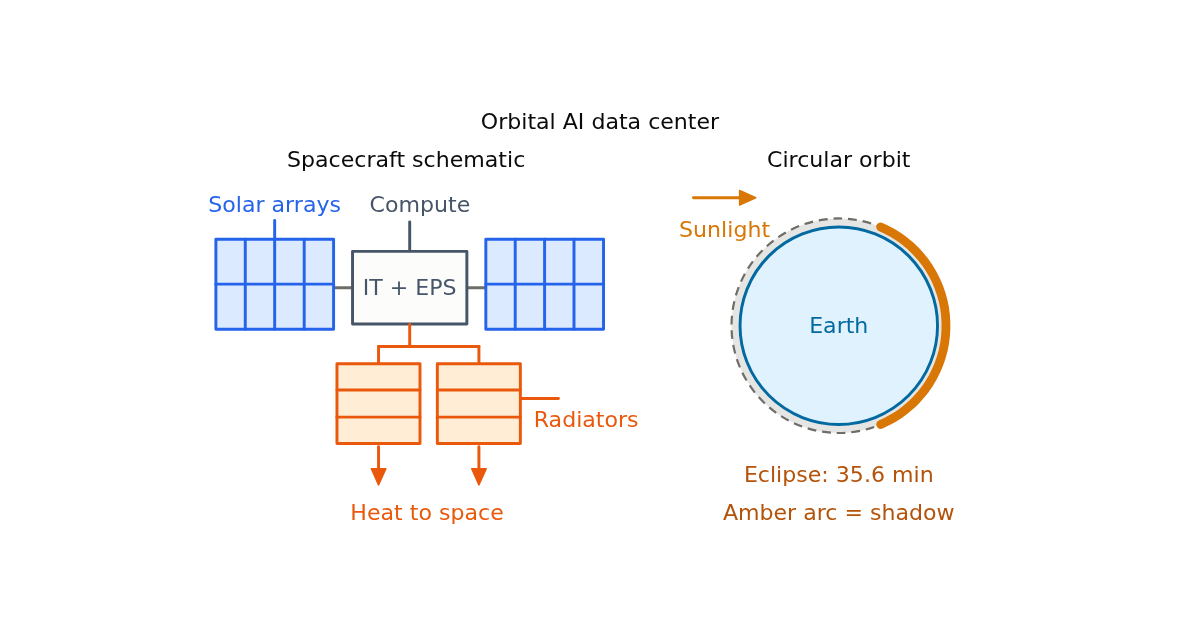
Wired White v2 Size solar arrays, eclipse batteries and radiators for an orbital AI data center. Compare temperature, orbit geometry, launch mass and launch-price assumptions.
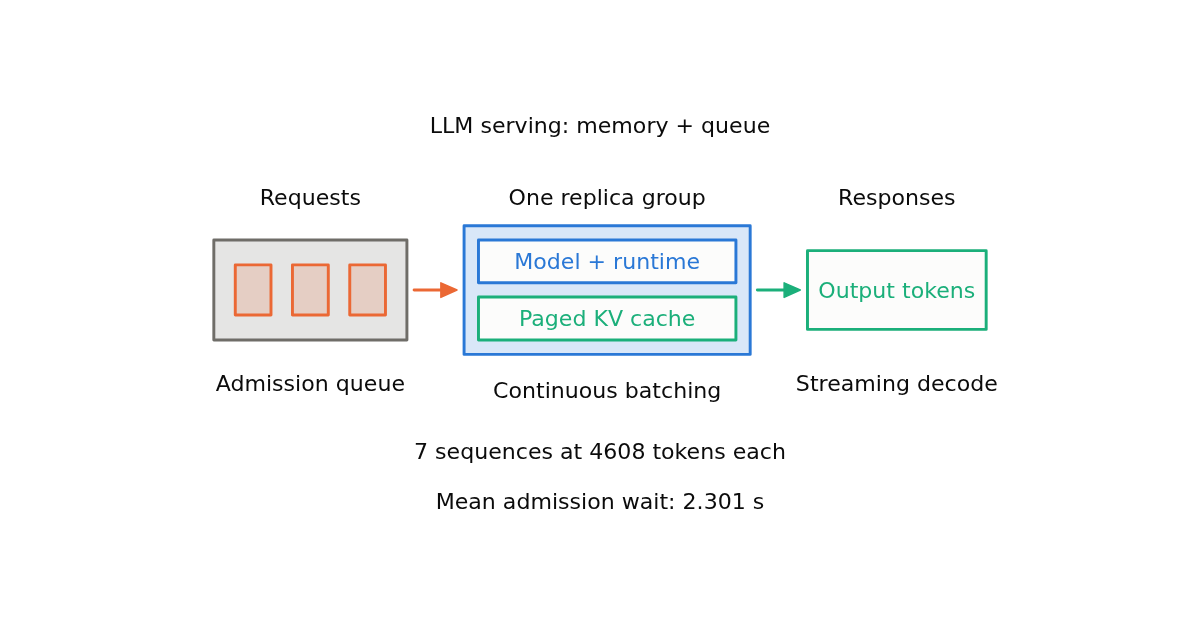
Wired White v2 Estimate KV cache capacity, concurrent requests, queue delay and streaming latency. Compare parallel agent completion and cost against local server and API limits.
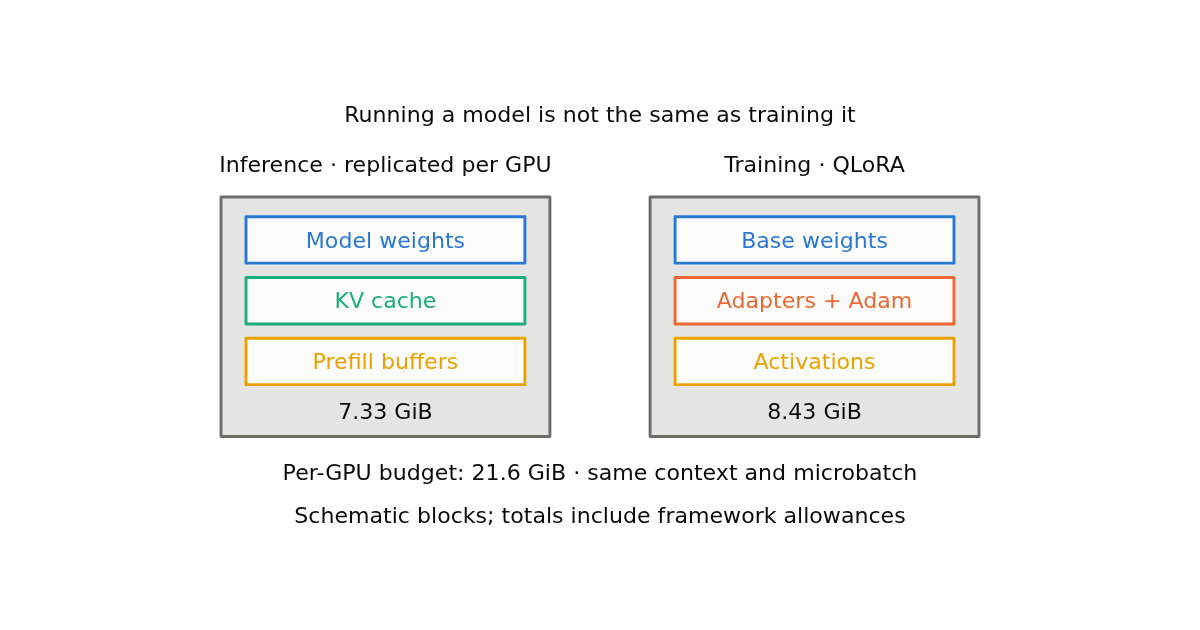
Wired White v2 Estimate inference and training VRAM, maximum sequence length and microbatch, runtime and cost for full fine-tuning, LoRA and QLoRA. Compare GPU sharding, checkpointing and editable MFU assumptions.
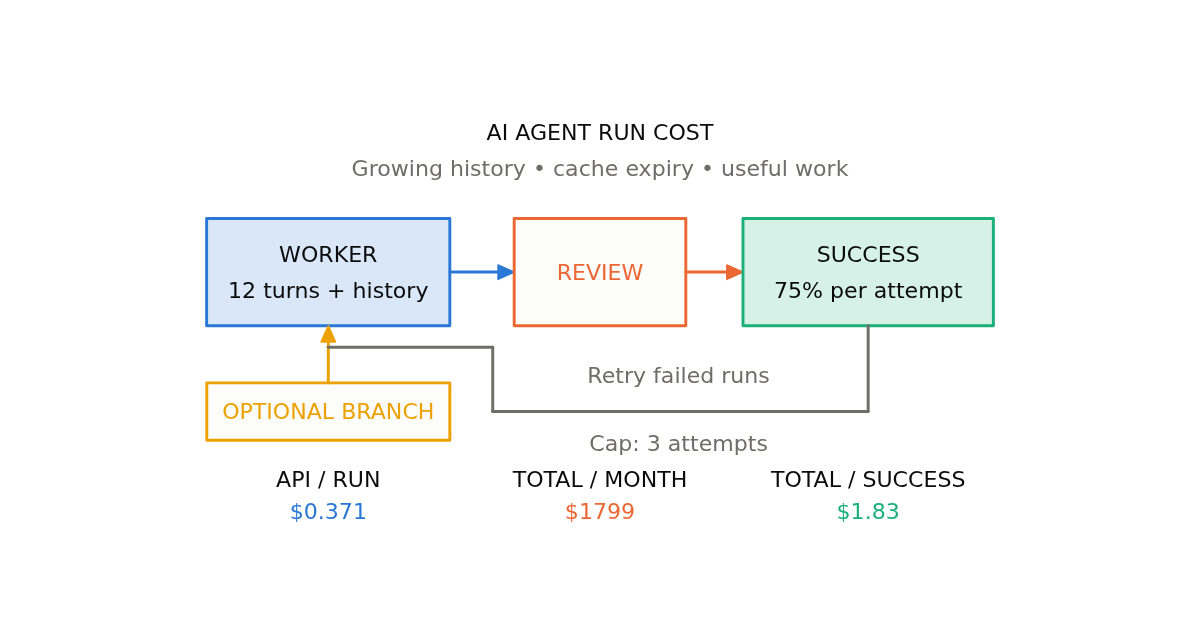
Wired White v2 Estimate AI agent costs with growing history, cache expiry, mixed models, retries and human review. See cost per run, per month and per successful task.
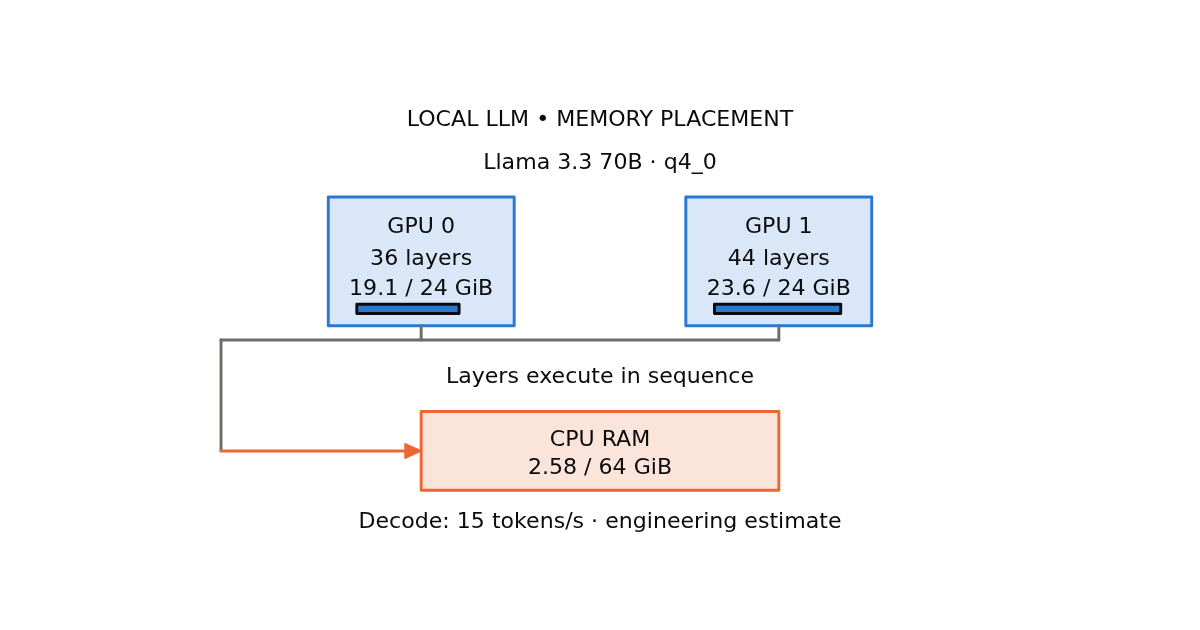
Wired White v3 Compare 2×3090, RTX 5090 and Apple silicon. Plan layers, tensor parallelism or MoE experts in RAM, with per-device memory, prefill/decode estimates and cited benchmarks.
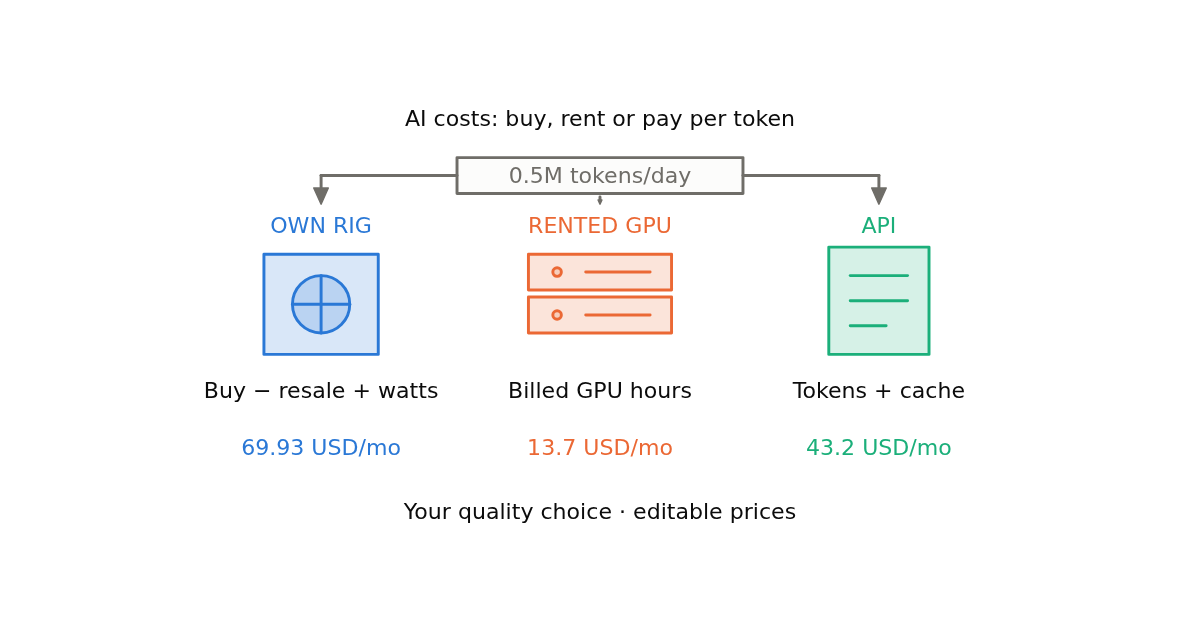
Wired White v2 Compare owning an AI rig, renting a GPU and using an API. Include prefill, decode, idle power, resale, upkeep, caching and reasoning tokens to find cost per million tokens and break-even.
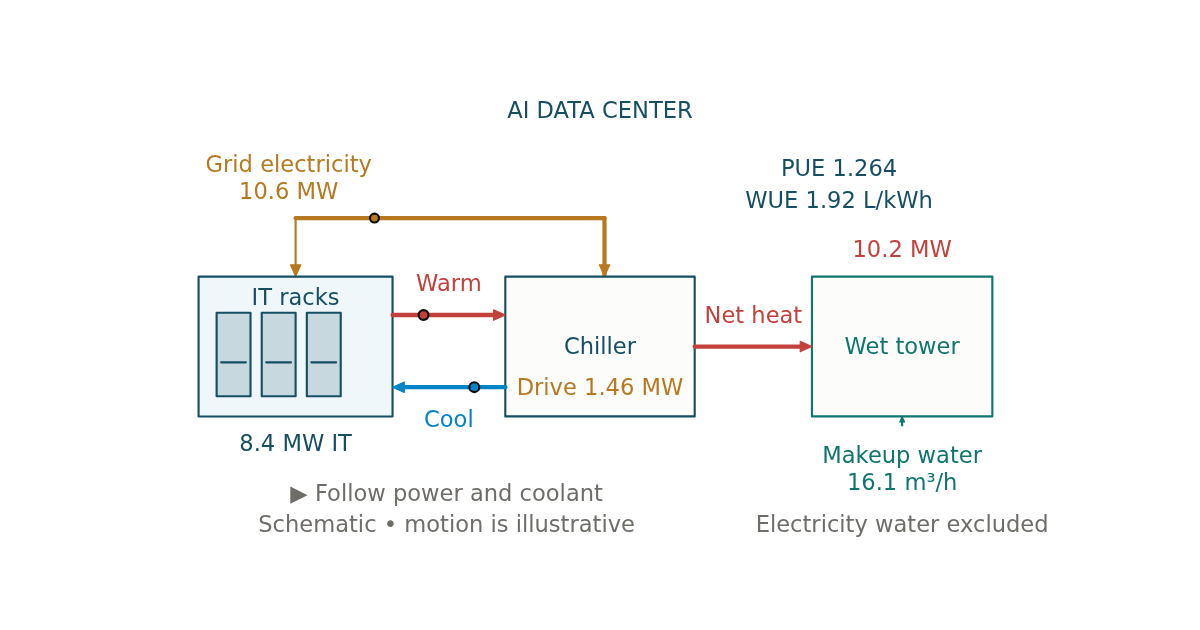
Wired White v2 Estimate AI rack power, grid draw, cooling duty and water use. Compare wet towers, air-cooled chillers and dry cooling with PUE, WUE and annual totals.
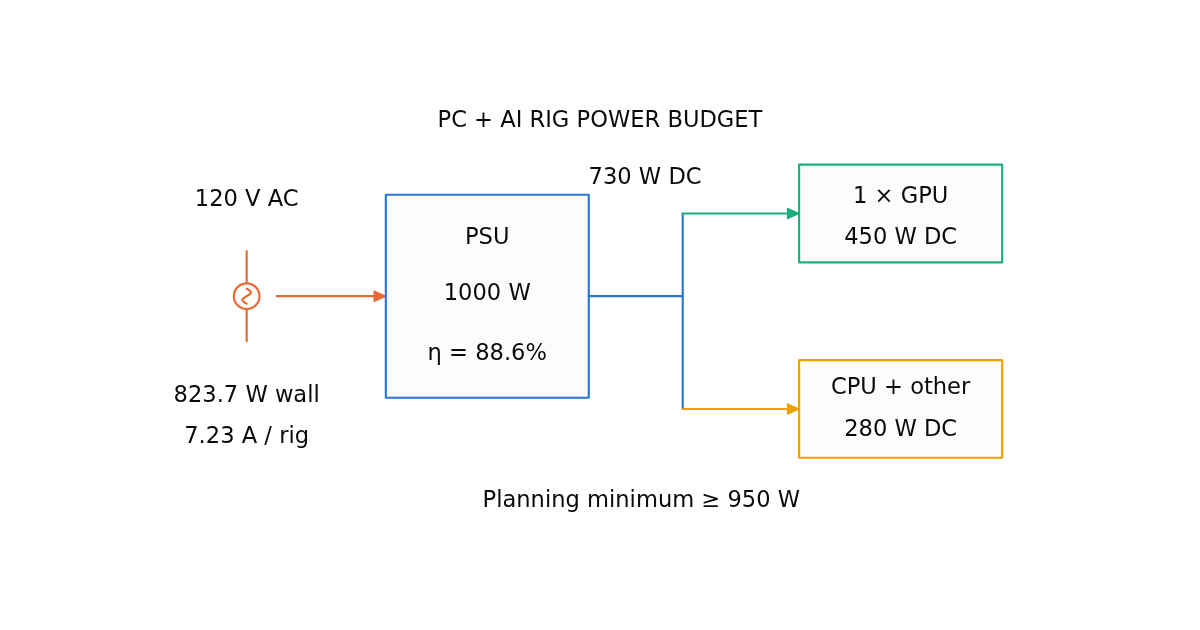
Wired White v2 Size a PC or multi-GPU AI rig PSU from wattages, check ATX 3.1 transients, estimate wall power and yearly cost, and explore 12V-2x6 contact heating.
Wired White v2 Find which local LLMs fit your GPU, Mac or CPU—or which hardware fits a model. Compare KV memory, prefill, decode, runtime support and measured speed references.
Please confirm you want to block this member.
You will no longer be able to:
Please allow a few minutes for this process to complete.